
Narration, dialogue and ads in a voice that fits. Preview every voice before you use it.
Dubbing · voice · music · transcriptsYour video, in another language.
Your video, in another language.
The dubbed audio, back in about a minute.
On the Dub page, upload your file and pick a language, and Omnibo returns the dub as an audio file. It does not return a video and does not sync lips. In 4 test jobs on 5 November 2026, files of 16 to 20 seconds each came back in about a minute.
Dubs, voices,
music and transcripts.
Dub a file into another language
Upload it on the Dub page and pick a language. You get the dubbed audio file back, not a video, and it does not sync lips. Dubbing v1 costs 600 cr / minute and needs Starter or higher; Dubbing v2 costs 2,640 cr / minute and needs Pro or higher.
Speech in many voices
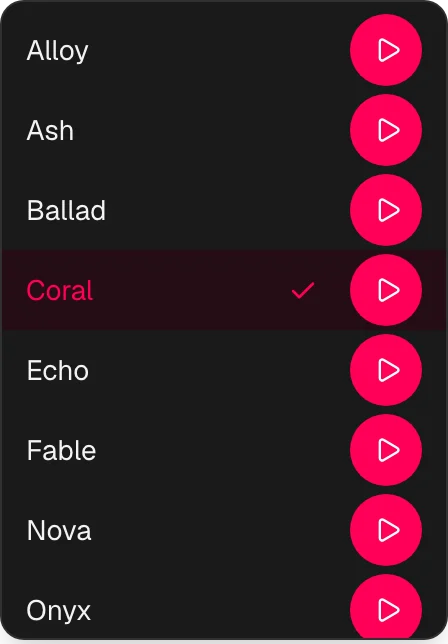
Narration, dialogue and ads read by voices you can preview before you choose. Clone a voice you have permission to use.
Music, sound effects, transcripts
Score a scene, add the sound effect it needs, or turn a recording into clean, timed text.
Asking for a dub in chat does not use this page. A job takes 10 minutes at most. The page opens on Dubbing v2; pick Dubbing v1 for the lower rate.
Choose from 32 audio models from 8 providers, each with its published rate.
See every modelVoice & audio,
the way you work.
Turn text into speech, score a scene with music or sound effects, transcribe a recording, or clone a voice you have permission to use.
01 / 04
Text to speech
02 / 04
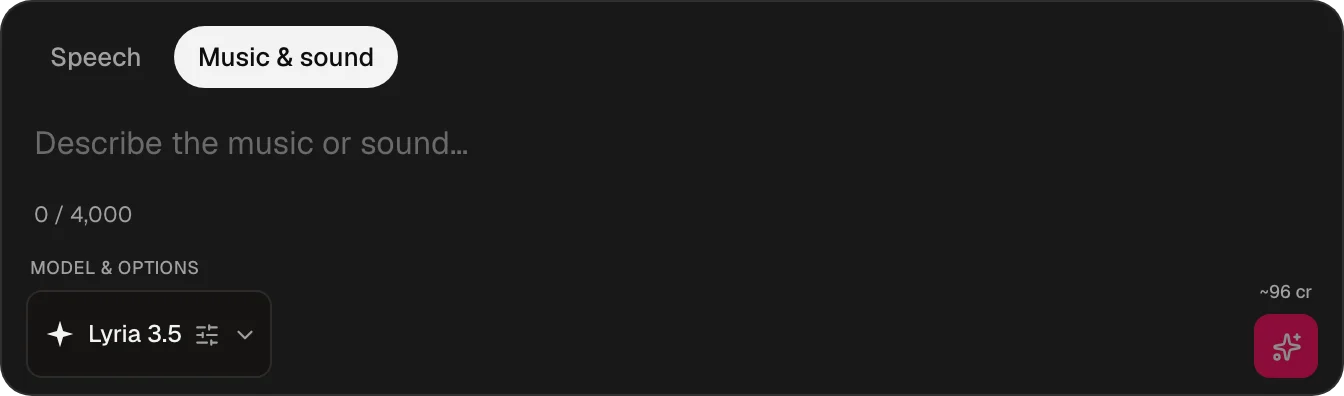
Music and sound
Score a scene or add the sound effect it needs, from the same composer.
03 / 04
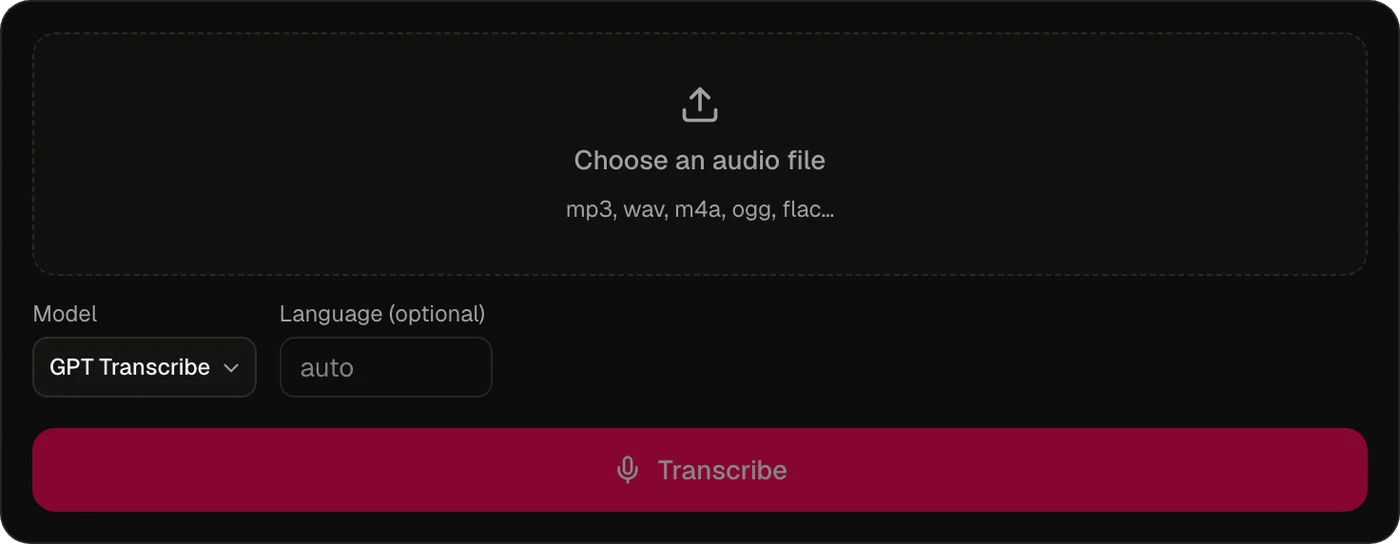
Transcribe any recording
Drop in an audio file, pick the model and, if you like, the language, and get clean, timed text back.
04 / 04
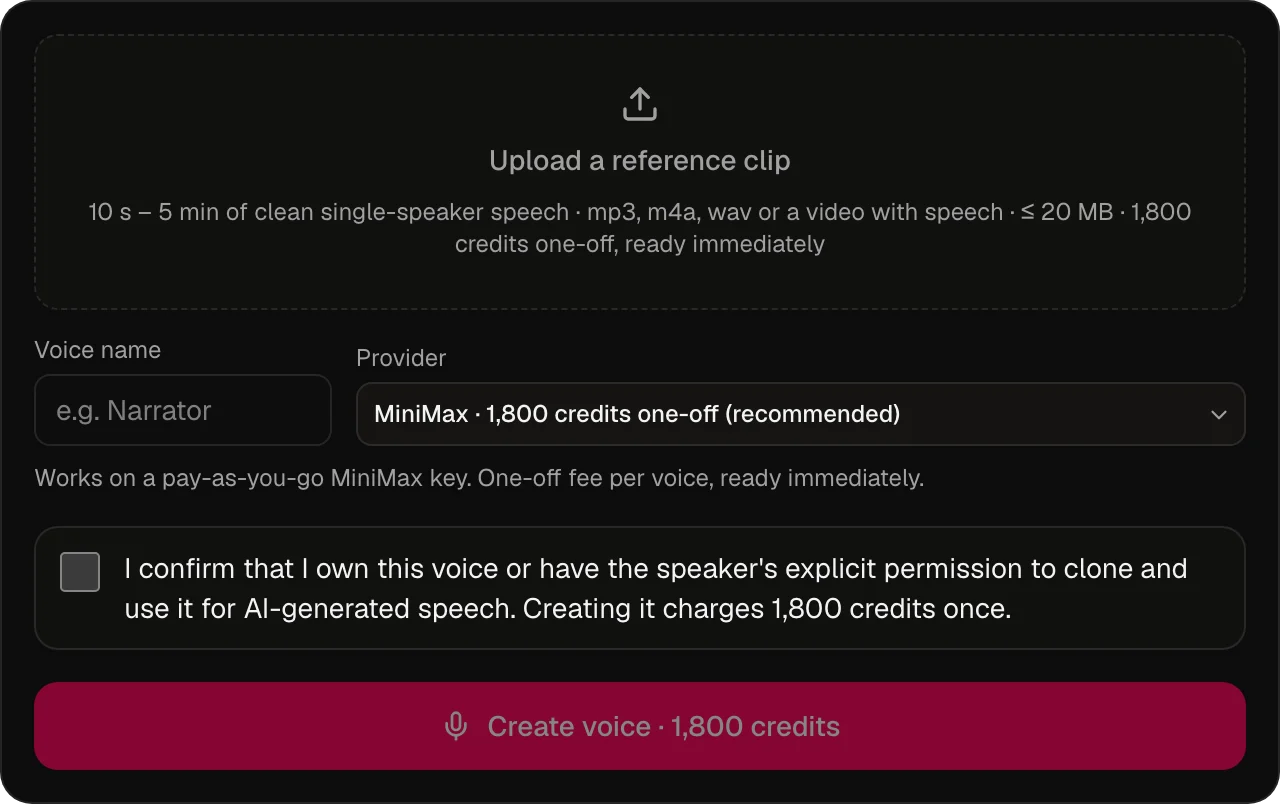
Clone a voice
Upload a short reference clip you have permission to use, name the voice, and speak with it from then on.
Hear it
for yourself.
Real speech from the community feed, each with the model and voice that read it.
32 audio models.
Each with its rate.
Every model, its provider, its published rate, the plan it needs and the day it arrived.
 ElevenLabs9 audio models
 fal.ai7 audio models
 Google5 audio models
 OpenAI4 audio models
 ByteDance2 audio models
 MiniMax2 audio models
 xAI2 audio models
 Kling AI1 audio model
ModelProviderRatePlanAdded
Questions,
answered.
Which audio models does Omnibo have?
32 audio models from 8 providers: ElevenLabs, fal.ai, Google, OpenAI, ByteDance, MiniMax, xAI, Kling AI. The newest is ElevenLabs Sound Effects v3, added 5 November 2026.
What does an audio generation cost?
Every model has its own published rate. The table above lists every rate and its unit.
Can I clone my own voice?
Yes. Record a short sample and use your voice for any text.
Can Omnibo transcribe a recording?
Yes. Turn any recording into clean, timed text.
Your next idea
starts here.
Create a free account, no card needed. Upgrade when you want more.
Create a free account →